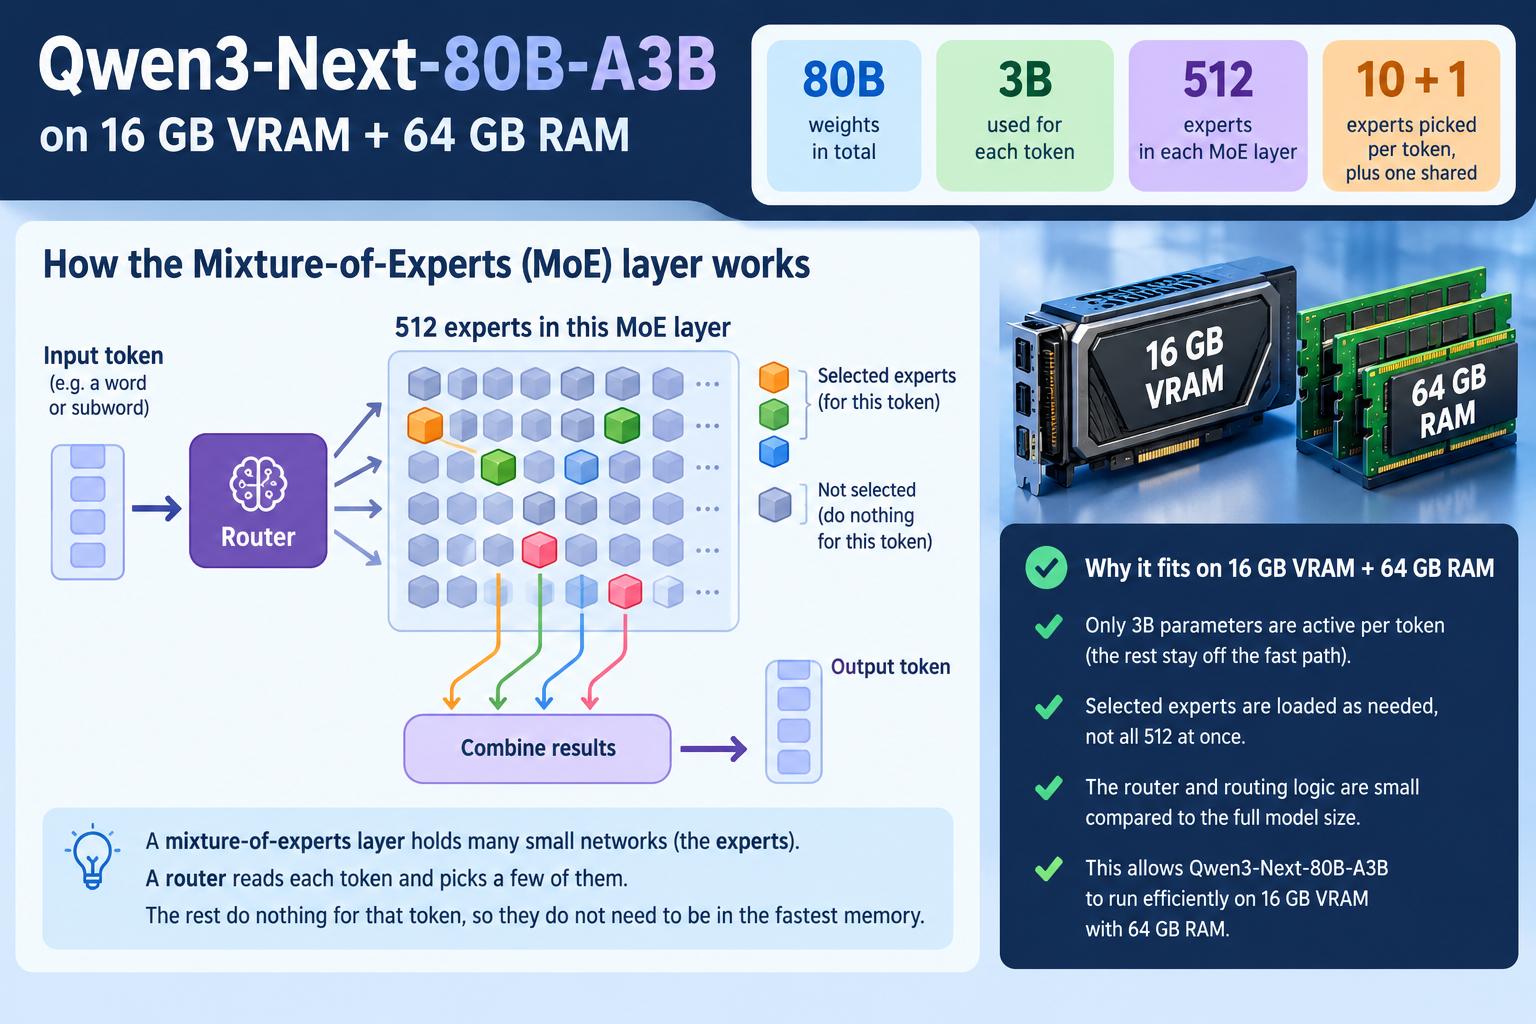
A mixture-of-experts layer holds many small networks, the experts. A router reads each token and picks a few of them. The rest do nothing for that token, so they do not need to be in the fastest memory.
Three places to keep weights
Try it: where do the 10 experts live?
One layer is drawn as 512 squares. Change the size of the model file and see how the squares split across the three tiers. Then send a token.
Illustration, not a measurement. Assumptions: about 12 GB of VRAM and 56 GB of RAM are free for experts, experts are spread evenly, the router picks them at random, and the 3B active weights at 4-bit (about 1.8 GB) are read once per token at 896 GB/s from VRAM, 40 GB/s from RAM and 4 GB/s from the SSD. Real routing is uneven and real programs differ, so treat the speed as an upper bound for the idea, not a forecast.
What to remember
- A 4-bit copy of this model is about 45 to 50 GB. That fits in 64 GB of RAM, so the SSD is rarely touched.
- A model larger than RAM must read experts from the SSD again and again. Then the SSD speed sets the token speed.
- Programs differ. Many, such as llama.cpp, put fixed groups of weights in VRAM and RAM and let the operating system load the rest from disk. Only some move single experts between tiers while running.
The GPU in this example: RTX 5070 Ti
| Spec | Value | Why it matters here |
|---|---|---|
| Video memory | 16 GB GDDR7 | The VRAM tier. Anything larger spills into RAM. |
| Memory bus | 256-bit | Together with the memory speed, sets the bandwidth. |
| Memory speed | 28 Gbps per pin | 256 bits x 28 Gbps / 8 = 896 GB/s. |
| Memory bandwidth | 896 GB/s | The VRAM speed used in the estimate above. |
| Host link | PCIe 5.0 | The path between the GPU and system RAM. |
Source for the model figures: Qwen3-Next-80B-A3B model card (80B total, 3B active, 512 experts, 10 active, 1 shared).